The problem was not reading more headlines. The problem was isolating signal from noise and answering only from real evidence.
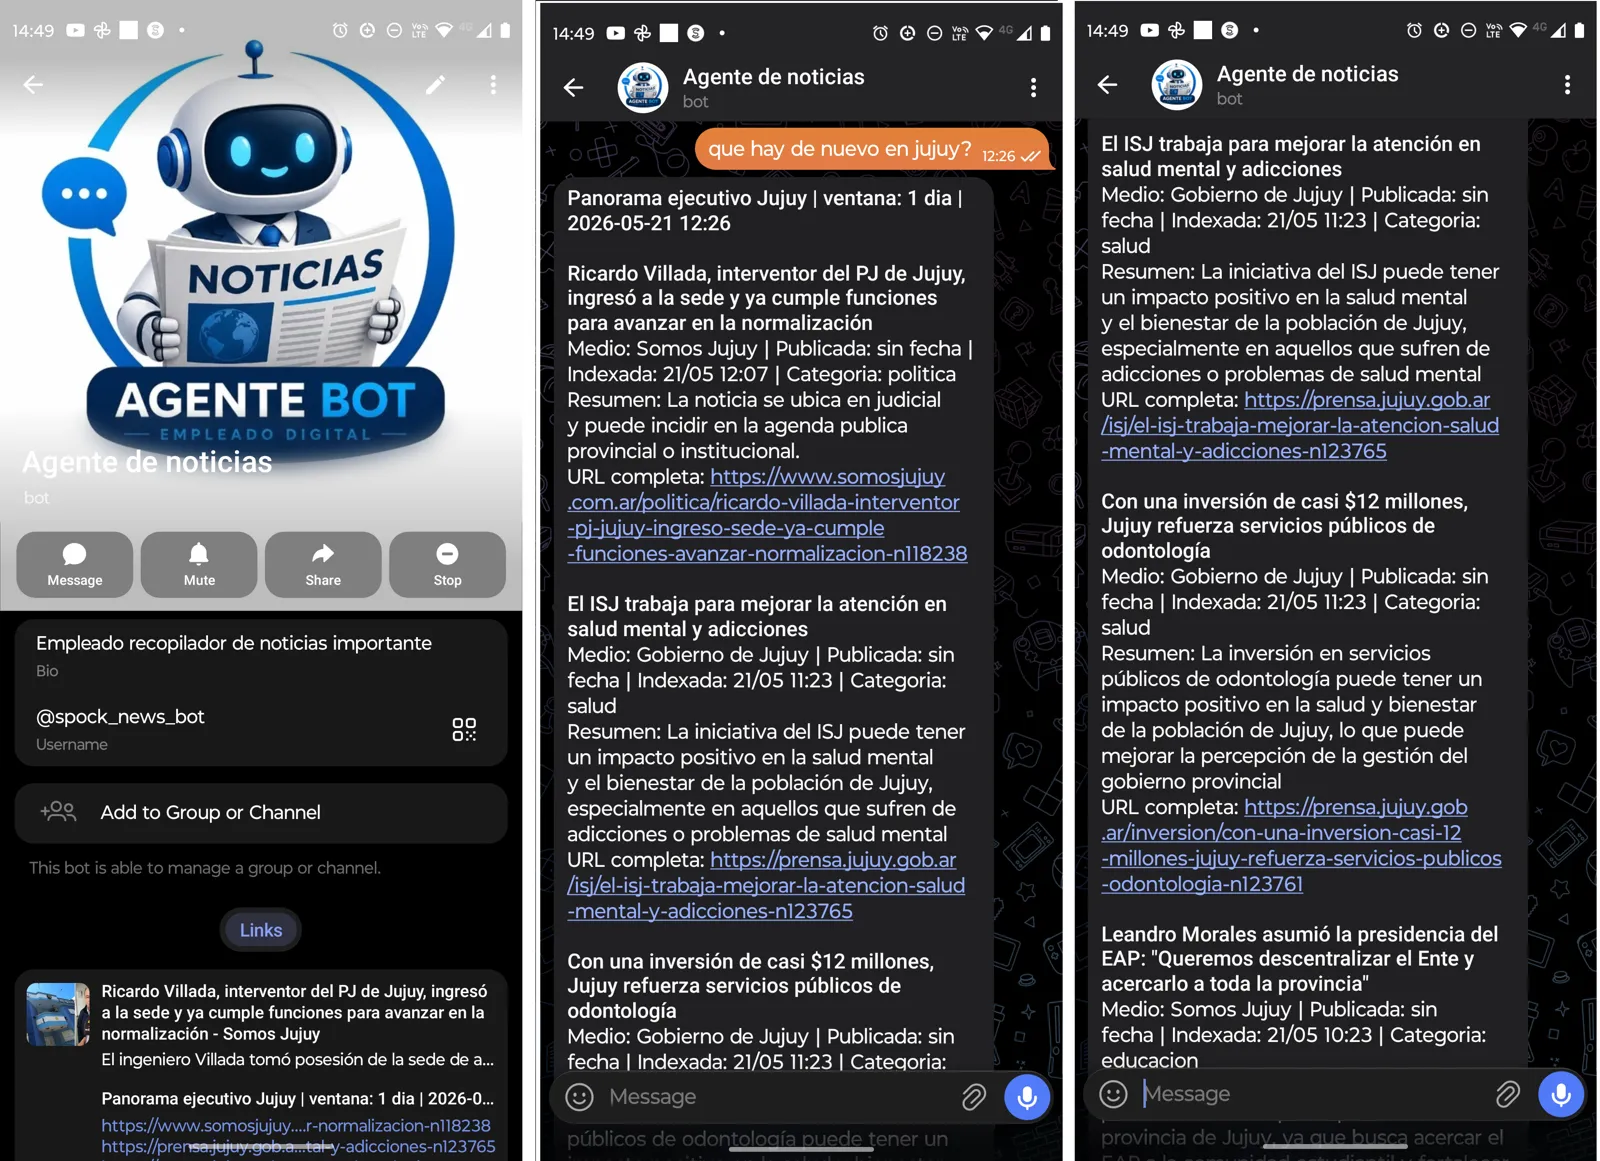
MENDINEWS Agent is a personal executive intelligence platform built for news monitoring. It ingests RSS and web content, extracts readable text, scores political and social relevance, generates executive digests, stores embeddings in PostgreSQL with pgvector, and exposes a closed RAG chat that answers only from indexed news.
Real problem#
Institutional teams and decision makers do not need more raw headlines. They need signal detection, contextual prioritization, and reliable answers. Reading fragmented portals and relying on human memory produces operational noise and weakens trust.
Solution#
I designed an executive intelligence pipeline that monitors sources, extracts content, scores relevance, generates structured digests, and enables conversational querying only over indexed evidence. The architecture optimizes for institutional reliability before conversational fluency.
What the app is#
MENDINEWS Agent operates as a monitoring, enrichment, and retrieval platform for news. It is not a generic chatbot. It is an evidence-first system that collects articles, normalizes content, produces executive summaries, and only then exposes semantic search and grounded question-answering.
Core capabilities#
RSS and web scraping with extraction fallback chain.
AI classification by category, importance, sentiment, and tags.
Executive summaries for high-signal briefings.
Embeddings and semantic retrieval in PostgreSQL with pgvector.
Closed RAG chat over indexed news only.
Telegram delivery and WhatsApp-ready webhook architecture.
Scheduled scraping, digest, health-check, and deploy preflight flows.
Technical base (stack)#
| Technology | Role in the system |
|---|---|
| Python 3.12 | Primary runtime for API, jobs, and orchestration |
| FastAPI | HTTP API layer and OpenAPI surface |
| PostgreSQL | Relational persistence for articles and metadata |
| pgvector | Embeddings and similarity search |
| Groq API | Classification, summaries, and grounded answers |
| APScheduler | In-process scheduling for scraping and digest |
| Telegram Bot API | Executive delivery and command interface |
| Docker + Compose | Portable runtime for local, VPS, and cloud |
| GitHub Actions | Automation for scraping, digest, and deploy preflight |
Project structure#
`app/scrapers/`: RSS discovery, source registry, and fallback extraction chain.
`app/ai/`: classification, summarization, embeddings, and closed RAG.
`app/db/`: SQLAlchemy models, pgvector bootstrap, and retrieval queries.
`app/messaging/`: active Telegram delivery and WhatsApp-ready contract.
`app/jobs/`: scheduled scraping, morning digest, and health workflows.
`app/main.py` and `app/cli.py`: HTTP and non-interactive operational entrypoints.
System architecture#
The application is built as a pipeline. RSS and web scraping feed an extraction layer; then classification, summaries, and embeddings enrich each article; PostgreSQL + pgvector sustain retrieval and similarity search; finally the chat answers only if retrieved evidence crosses thresholds and survives post-generation validation.
Scraping → extraction → classification → embeddings → storage → retrieval → grounded generation.
Vector retrieval filtered by similarity, recency, source allowlist, and contextual reranking.
API, Telegram, jobs, and GitHub Actions share the same operational entrypoints.
Anti-hallucination strategy#
There is no direct user → LLM answer path: retrieval always happens first.
Minimum similarity threshold before grounding is allowed.
The model receives structured evidence JSON, not an unconstrained context blob.
Valid answers must include citations coherent with retrieved evidence.
Temperature 0.0 plus explicit abstention when context is weak or contradictory.
Abstention response: “No encontré información suficiente en las noticias indexadas.”
Functional surface#
`GET /health`: service health and indexed volume.
`GET /news/latest`: most recent indexed articles.
`GET /news/search`: keyword search across title, summary, and content.
`POST /chat`: closed RAG query with citations and grounded flag.
`GET /digest/today`: current digest payload.
`POST /integrations/telegram/webhook` and `GET /integrations/whatsapp/webhook`: channel contracts.
Operations and deployment#
The platform is prepared for local runs, Docker, VPS, and managed providers such as Railway, Render, or Fly.io. The architecture separates the web API from scheduled automation: the web layer serves retrieval and health, while GitHub Actions can handle scraping, digests, and deploy preflight without competing with chat traffic.
Project summary#
I built MENDINEWS Agent as an evidence-first information intelligence system for executive monitoring. I designed the FastAPI surface, the scraping and extraction pipeline, the classification and summary layer, semantic persistence with PostgreSQL + pgvector, Telegram integration, and a closed RAG architecture with abstention, citations, and post-generation validation.
If your team is building reliable information products with RAG and operational automation, this is the kind of system I want to keep shipping.
I work best where architecture, technical judgment, and output reliability matter more than superficial demos.